
About ToneBench
ToneBench was built to show which AI models can write a full YouTube script in one established voice, and at what cost. Louis-François Bouchard and the Towards AI team maintain it.
Why ToneBench Exists
Choosing a model for scripted writing needs evidence that general benchmarks do not provide.
Broad Leaderboards Miss Voice
Public leaderboards rank general preference across many tasks. They do not show whether a model keeps one voice, one structure and one level of technical depth across a full script.
Channel Scripts as the Reference
Each of the 10 briefs uses a real What's AI script, reviewed by the Towards AI team, as its reference. Half come from published videos and half are unpublished. Drafts are compared with writing held to the channel's publishing standard.
Quality Weighed Against Cost
Each configuration's Writing Score, the 0 to 100 consensus of the judges and code, appears next to its cost and time per script, so quality can be weighed against price and reasoning effort.
Who ToneBench Is Designed For
Four groups, each with a starting point on this site.
Creators and Script Writers
Choosing a model to draft long-form video scripts. The ranking gives a shortlist to test against a writer's own voice.
View the leaderboard →Engineering and Product Teams
Selecting a model for a writing feature, where cost and time per script matter alongside quality.
Compare reasoning settings →Editorial and Content Teams
Deciding where a model can draft on its own and where an editor still needs to step in, metric by metric.
Browse model scorecards →Evaluation Researchers
Studying LLM judges and writing evaluation. The methodology documents the judge panel, the confidence intervals and the validation checks, and the judge analysis measures each judge's lab preference and agreement.
Read the methodology →Who Maintains ToneBench
Louis-François Bouchard maintains the benchmark with the Towards AI editorial team, who reviewed every reference script.
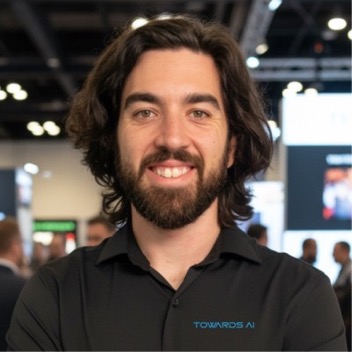
Louis-François Bouchard
Co-founder and CTO, Towards AI · Host of What's AI on YouTube
Builds and maintains ToneBench. The reference scripts come from his What's AI channel, which explains AI engineering, and the style guide every model receives is built from his voice and storytelling guides.
Experience Behind the Benchmark
Towards AI's teaching record, and the parts of the team's work that the benchmark relies on.
Source: Towards AI Academy about page, October 2026.
The Voice Owner Sets the Standard
The voice under test belongs to the benchmark's maintainer, so the standard for tone, structure and depth comes from the person who writes in it.
Six Reviewers and a Final Edit
Every reference script was reviewed by:
- 2 AI engineers
- 1 professional writer
- 2 YouTube reviewers
- 1 fact checker
- Final edit by the content lead
Pipeline Built From Course Material
The generation and scoring pipeline is adapted from the writing and evaluation part of a Towards AI engineering course.
How to Take Part
Ways readers can check, correct and extend the benchmark.
Report an Error
Email wrong figures, broken pages or methodology concerns, with a link to the page in question.
Email a correction →Suggest a Model
Name the model and its provider. New models go through the same generation and judging pipeline as every configuration on the board.
Email a suggestion →Follow Board Updates
New models, board changes and analysis, published as an RSS feed.
Subscribe to the feed →Frequently Asked Questions
Who Maintains the Benchmark?
Louis-François Bouchard maintains ToneBench with the Towards AI team. Each board release passes a human editorial review before publication, and each change to the code goes through a reviewed pull request.
How Are the Reference Scripts Reviewed?
Each reference script is a team-reviewed What's AI script. Half of them come from published videos and half have not been published. Which is which is not disclosed, and the site names scripts only by number and type. AI assisted with parts of the drafting, and the final versions are mostly human-written and edited. The six reviewers listed under Experience Behind the Benchmark worked on each script together and did not score it separately, so no inter-rater reliability figure is available. The methodology page gives the details.
Is the Benchmark Independent of Model Providers?
Towards AI runs ToneBench and does not develop the models it ranks. Every configuration receives the same prompt and is scored by the same four judges: three LLM judges from three labs, each of which also has models on the board, plus Jev, a typed judge from TypeSafe, which has none. No draft is scored by its own lab alone. The judge analysis measures how much each LLM judge favors its own lab. Models are run through their public subscriptions and APIs, and cost per script uses public list prices.
What Is the Intended Scope of the Benchmark?
ToneBench measures one skill: writing a full YouTube script about AI in one established voice, from a brief and a research packet. Every ranked configuration writes the same 10 real scripts, five drafts each. The results do not measure general intelligence, coding or other writing formats, and they describe closeness to one creator's voice. For a different voice, the ranking serves as a shortlist for testing.
How Can Readers Contribute or Report Issues?
Send corrections, wrong figures, methodology concerns or model suggestions to [email protected]. The How to Take Part section lists each option.